What this project is
Edge multimodal LLMs compress vision tokens 4x/16x to fit device budgets. Across 960 probes and a 31.7x token-budget axis (82–2,598 tokens), compression trades away per-element binding before global structure: digit reading and coarse detection survive at 82 tokens, while counting and fine-gap localization collapse below ~350 tokens. The cleanest cliff: ring-gap localization. The headline cell was re-measured at n=200 (200 seeds vs the n=20 scan): the aggregate cliff drops 0.963 → 0.770 (z = 13.9), the V-shaped failure at 82 tokens survives and is significant on the hardest difficulty (0.33 → 0.46, non-overlapping 95% CIs), and the n=20 magnitudes (0.95 → 0.10) are corrected to 0.78 → 0.33.
Read the technical report →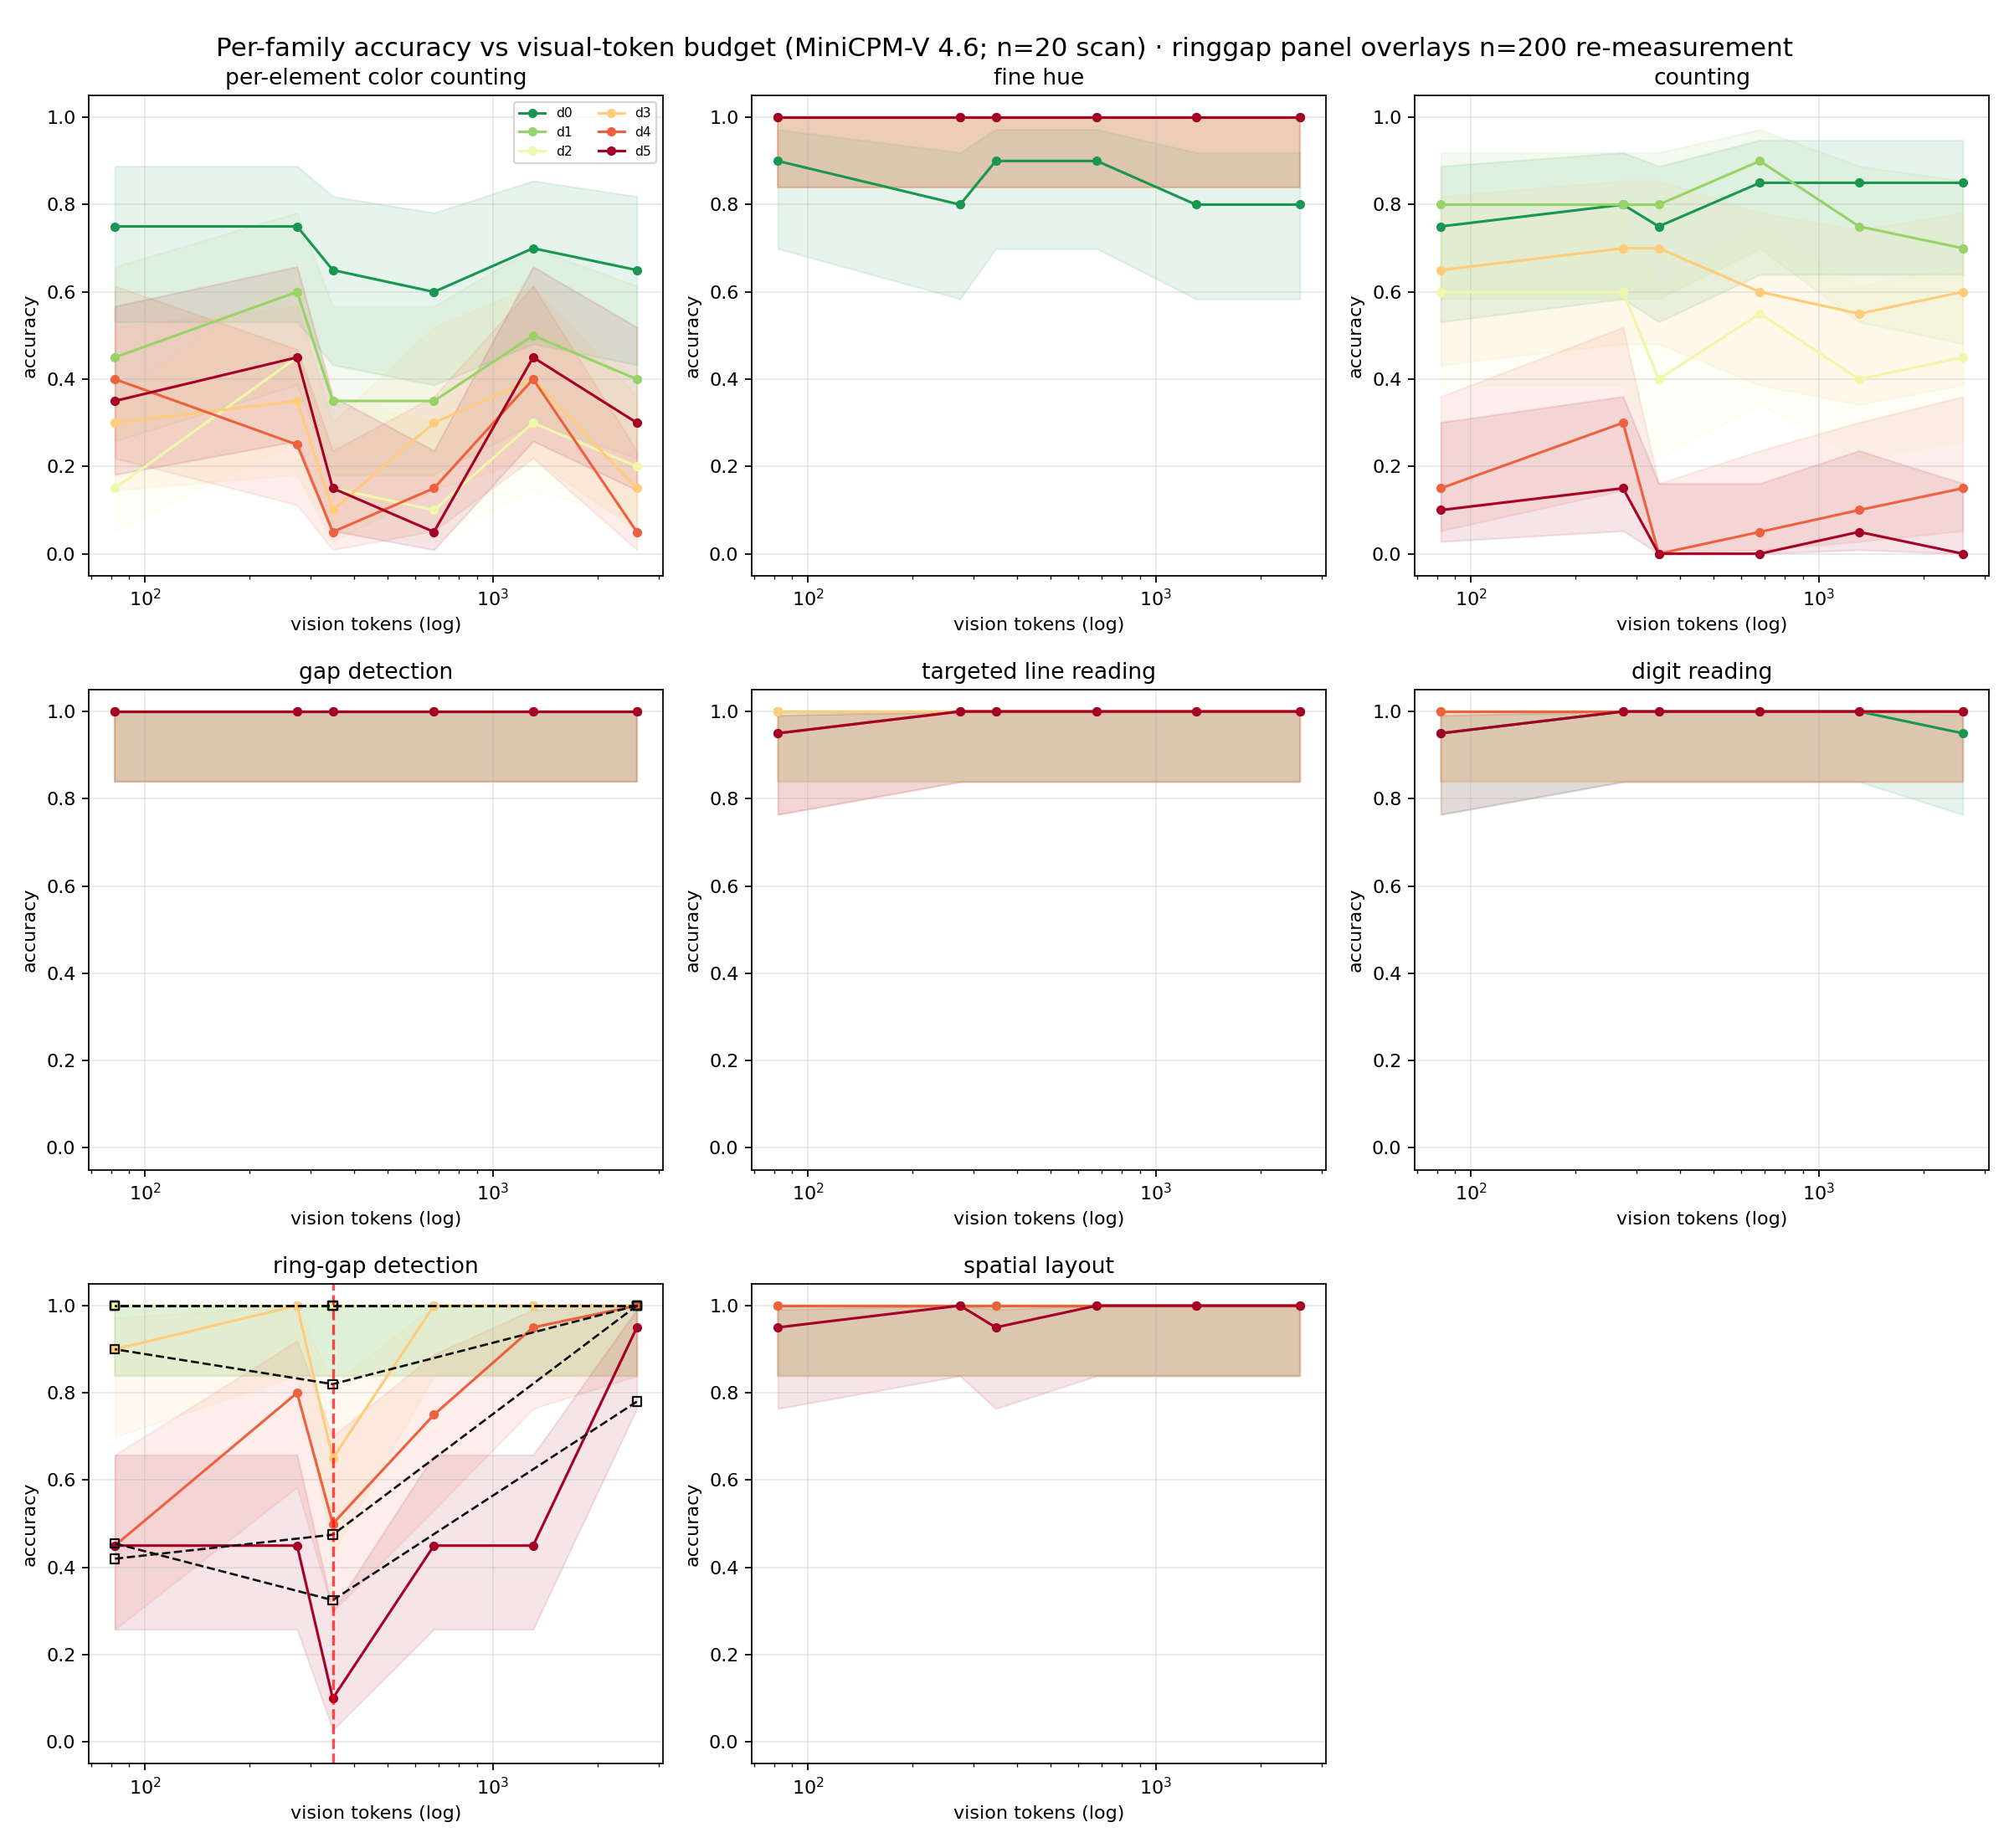
Credibility at a glance
960 probes · 6 budgets (82–2,598 tokens) · n=20 scan + n=200 cliff re-measurement